DocsShaping data
Remove duplicates
Keeps the first row for each key and drops the rest. It makes no API calls. On Starter, Pro and Business.
Settings
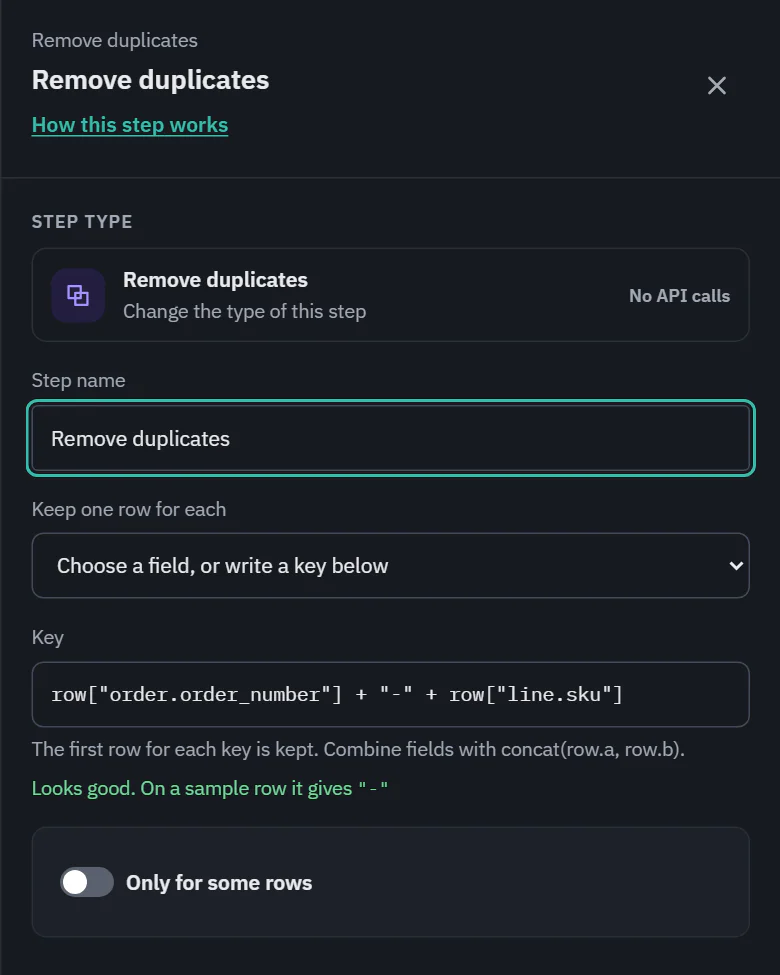 (opens the full size image in a new tab)
 (opens the full size image in a new tab)
- Keep one row for each: choose the field that identifies a duplicate, from the fields the step receives.
- Key: the expression behind it, such as row.order_id. To tell rows apart by more than one field, combine them: concat(row.a, row.b). The first row for each key is kept.
Ladeworks remembers a short fingerprint of each key, not the rows, so a very long file does not take much memory. It does stop at 2,000,000 different keys, with "Remove duplicates found more than 2,000,000 different keys. Split the data into smaller runs, or filter it before this step."
Use Only for some rows to apply it to part of the data. On Pro and Business.
Cost and the run line
No API calls. The run line reads "93 kept, 27 duplicates removed".
For records that must never be sent twice across runs, use "Don't send records that were already sent" on the Push step. Remove duplicates only works inside one run.